saved
The Harness Margin Opportunity
Hraness cites a source capture. The source author remains the source.
Venture capitalist at @theoryvc Student of Startups Backer of 9 unicorns Author of https://t.co/IWw3R3RVLm Subscribe https://t.co/iDgoLXaF98
The Harness Margin Opportunity
The better the harness, the better the business.
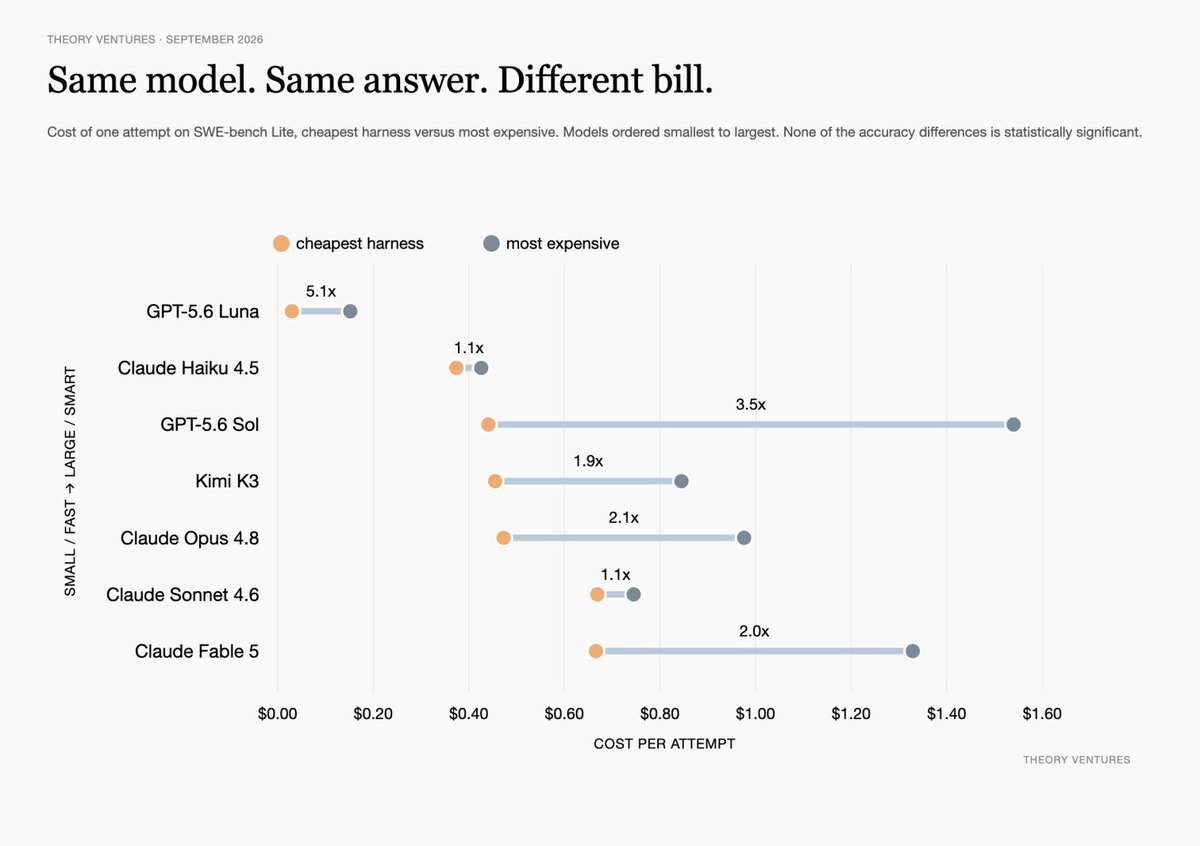
Berkeley published a study this week showing harnesses, the systems that control AI agents, set the price of an answer. The right harness cuts the cost of the same result by 71% without a loss of accuracy.
The data points to the opportunity for the next generation software applications: harnesses. Yes, we can use AI to do almost anything we want at work. But no, we cannot afford to provide everyone access to state of the art models for every task.
Harnesses coalesce common workflows into repeatable patterns: deterministic code or skills. The better the harness, the greater the compression, the lower the AI cost.
Imagine Theory buys a $250k a year contract for an AI associate to evaluate 5,000 companies. Two startups bid. Inferno calls a state of the art model on every step. Inferefficient runs a harness that coalesces the work into deterministic code, reserving the expensive model for the few steps that need it.
Inferno burns $131k on inference. Inferefficient burns $37k. Both carry the same cost for hosting, evaluations & the humans who check the work. Identical revenue, 38% gross margin against 75%.
Inferno cannot copy Inferefficient. Routing to a cheap model is only safe if you know which tasks it clears, & that knowledge comes from watching ten thousand versions of the same work. The cost advantage & the moat are the same asset.
Past 8,600 evaluations Inferno loses money on every additional one. It has to ration usage, which makes it the worse product at the moment the customer finds it most valuable. Inferefficient says yes to everything.
Gross profit buys growth. On a $250k contract that costs $150k to win, Inferno waits nineteen months to earn back the sale. Inferefficient waits ten. One of these businesses can hire twice as fast as the other.
Margins will not climb to 100%. As inference gets cheaper, buyers will ask more of their agents, shifting the equilibrium over time in response to competition. The gap between the two companies is what persists.
Effective harnesses are not cocktails of exotic ingredients: a deep customer understanding, a collection of relevant evals & a factory for automating hill climbing.
That’s a recipe for a valuable, defensible software company.
Same model. Same answer. Different bill.
THEORY VENTURES · SEPTEMBER 2026
Cost of one attempt on SWE-bench Lite, cheapest harness versus most expensive. Models ordered smallest to largest. None of the accuracy differences is statistically significant.
Horizontal cost-per-attempt axis from $0.00 to $1.60. Vertical axis Small/Fast → Large/Smart. Legend: orange = cheapest harness; grey = most expensive. Each model has a range bar labeled with the cost multiplier.
GPT-5.6 Luna — cheapest ~$0.02, most expensive ~$0.15, 5.1x
Claude Haiku 4.5 — cheapest ~$0.38, most expensive ~$0.42, 1.1x
GPT-5.6 Sol — cheapest ~$0.45, most expensive ~$1.55, 3.5x
Kimi K3 — cheapest ~$0.45, most expensive ~$0.85, 1.9x
Claude Opus 4.8 — cheapest ~$0.48, most expensive ~$0.98, 2.1x
Claude Sonnet 4.6 — cheapest ~$0.68, most expensive ~$0.75, 1.1x
Claude Fable 5 — cheapest ~$0.68, most expensive ~$1.33, 2.0x