saved
Jev changes a lot in memory & context engineering. Here's exactly how.
Hraness republishes this public post from a saved copy. The post is the author’s own words.
founder @supermemory.com, the memory/context guy
Jev changes a lot in memory & context engineering. Here's exactly how.
Everyone is talking about how Jev (a new system 1 model by @typesafeAI that's really good at fast decisions) is changing computer use, browser use, labelling and many other things. It's exciting times, and it feels like a completely different paradigm of models.
I've been working on agent memory for the last 3 years, and the founder of @supermemory. Things like this completely change the dynamics of what we do at supermemory and how memory works in general (there's no right answer yet :))
So, we decided to explore how Jev can change, optimize, or improve our systems, or help us rethink how we do memory, and it's actually a lot of things throughout the pipeline!!
gonna be a fun and a long read - so buckle up!
how people do memory right now.
Before we get into Jev-specific info, it helps to understand the general pipeline / methods people do memory, and then working backwards.
We looked at all popular memory systems right now (ChatGPT, Claude, Instinct, Openclaw, Hermes, Muse, etc.) and have been deconstructing / learning about them for a long time now. If you haven't yet, you should read my blog about instinct https://x.com/DhravyaShah/status/2101745550752428340
All 'memory' pipelines that we've observed at scale, and even our cusomers, have a few things in common. It doesn't really matter if it's Markdown-based, Graph-based, Fact-based etc, you can deduce it down to a few ~common points
Raw data (messages, files, tool output) ────────────→ Current context │ │ └→ Chunking / batching [fit into one model call] │ │ │ Observation / learning [off-loop] │ [background job, schedule, or trigger] │ │ │ Stored context │ [markdown files, vector DB, graph, KV] │ │ │ │ Summaries / profiles Search / reads ←── query ────┤ [one-pager, profile] [grep, cosine, on demand] │ │ │ │ └────────────────────┴──────────────────────┤ Harness injection [hooks, tools, system prompt, recaps] ─────┤ ↓ Agent's answer
- Finding relevant info / Retrieval It's not always retrieval as in RAG, but there almost always is a search step of sorts, which could be grep or cosine similarity
- Chunking the data in order to do the observation (you can't fit the whole thing in another model, so you would batch / chunk it). This also applies to retrieval
- Observation / learning happens outside of the 'main loop' (the main agent is not always deciding to learn things, it's at some schedule or trigger)
- Harness-specific logic to bring this context back into the model
When I do these explorations, I try to forget about supermemory's specific architecture and think from first principles.
And well, we found that -
In this case, Jev actually applies to all of the above!!!!!
Thinking about it, we figured that Jev really does help in most of these - (even if it's not practical in production in all of them yet), it decreases cost, increases accuracy, or makes things faster throughout the pipeline.
It may or may not be the absolute best at everything, but this is more of an exploratory post, so we'll talk about them anyways. And, I'll especially include the things that Jev is not good at.
The way to think about Jev is that it's really good at taking decisions really fast, and can output structured choices and probabilities. Not text generation.
Now, let's walk through them :)
Jev can make reranking better
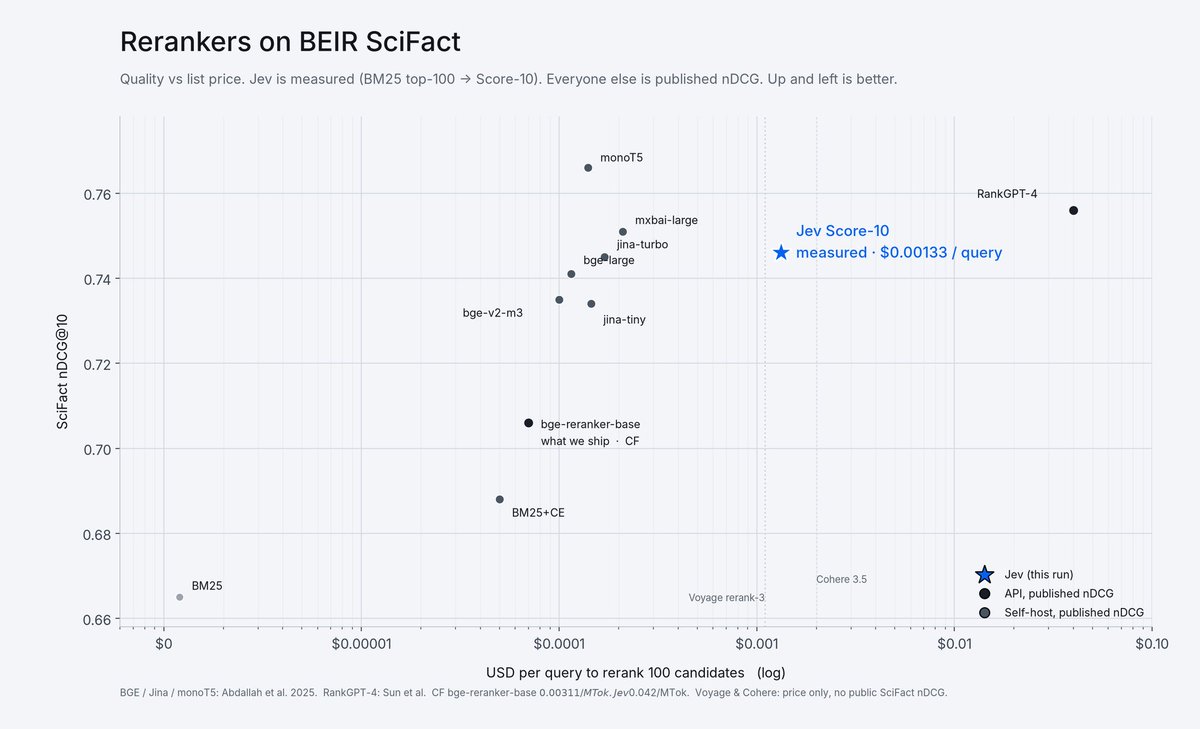
We compared Jev as a reranker against other rerankers on public BEIR sets.
We ran it through SciFact, NFCorpus, TREC-COVID, FiQA, SCIDOCS and some more benchmarks
Here's what we found.
- Jev always helped the first-stage list. On SciFact, NFCorpus, TREC-COVID, FiQA, SCIDOCS it beat base BM25 search every time - which was expected. (+0.05 to +0.17 nDCG@10).
We also tried different way of using Jev, and found that Noul-as-a-delete-gate failed (it kept nothing, for some reason). Noul-as-a-sort and Score-10 both worked (almost same); Score-10 was best among Jev-only methods (SciFact 0.751).
- It is not the quality winner #1, and it is not cheap vs BGE. But, the quality is much better than avg vs bge-reranker-base, for example: Jev wins quality on the 3 overlapping sets (mean 0.612 vs 0.564) and costs ~$0.00037/q vs ~$0.00002/q (~20×). vs jina-reranker-turbo: Jev loses the mean (0.612 vs 0.633). vs monoT5 / RankGPT-4 on SciFact: 0.751 vs 0.766 / 0.756.
And it's certainly better in quality than using any standard model for reranking.
- Cost sits next to Voyage, not next to BGE. Jev $0.042/MTok ≈ Voyage rerank-3 $0.05/MTok. Cohere is $0.002/q (5× Jev). RankGPT-4 is ~$0.04/q. The turbopuffer blog (Jev vs Voyage/Luna) is a different bakeoff; it never included BGE.
we always maintain the SOTA cost-quality ratio reranking at @supermemory, so if you're a customer you don't really have to care about this, and we will keep running evals and remain frontier!
@turbopuffer also did some work benchmarking these, https://x.com/ErikKaum/status/2103169247102812334 but they used GPT-5.6 sol Golden set to compare against, and we used public benchmarks.
Photo 1. Chart. Title: Rerankers on BEIR SciFact. Subtitle: Quality vs list price. Jev is measured (BM25 top-100 -> Score-10). Everyone else is published nDCG. Up and left is better. Y-axis SciFact nDCG@10 from about 0.66 to 0.78. X-axis USD per query to rerank 100 candidates (log) from $0 to $0.10. Legend: blue star Jev (this run); black API published nDCG; dark grey self-host published nDCG. Labeled points include monoT5 near top-left; RankGPT-4 high quality high cost (~$0.05/q); Jev Score-10 measured · $0.00133 / query near 0.75 nDCG; mxbai-large; jina-turbo; bge-large; bge-v2-m3; jina-tiny; bge-reranker-base labeled what we ship · CF; BM25+CE; BM25 near free; Voyage rerank-3 and Cohere 3.5 price-only markers. Footer: BGE / Jina / monoT5: Abdallah et al. 2025. RankGPT-4: Sun et al. CF bge-reranker-base 0.00311/MTok. Jev 0.042/MTok. Voyage & Cohere: price only, no public SciFact nDCG.
my tldr here is that reranker models are pretty good! Jev does score REALLY well here, but it's a bit more expensive and I'd stick to reranker for now. But in the decision models world, i can see it become SOTA
umm wait, one more thought ill put out there: Could reranking models be used as we use Jev, if you reframe the question as a ranking? they are pretty good and pretty cheap! idk, that's a discussion for another day
Perfectly accurate chunking, even across languages and messy data
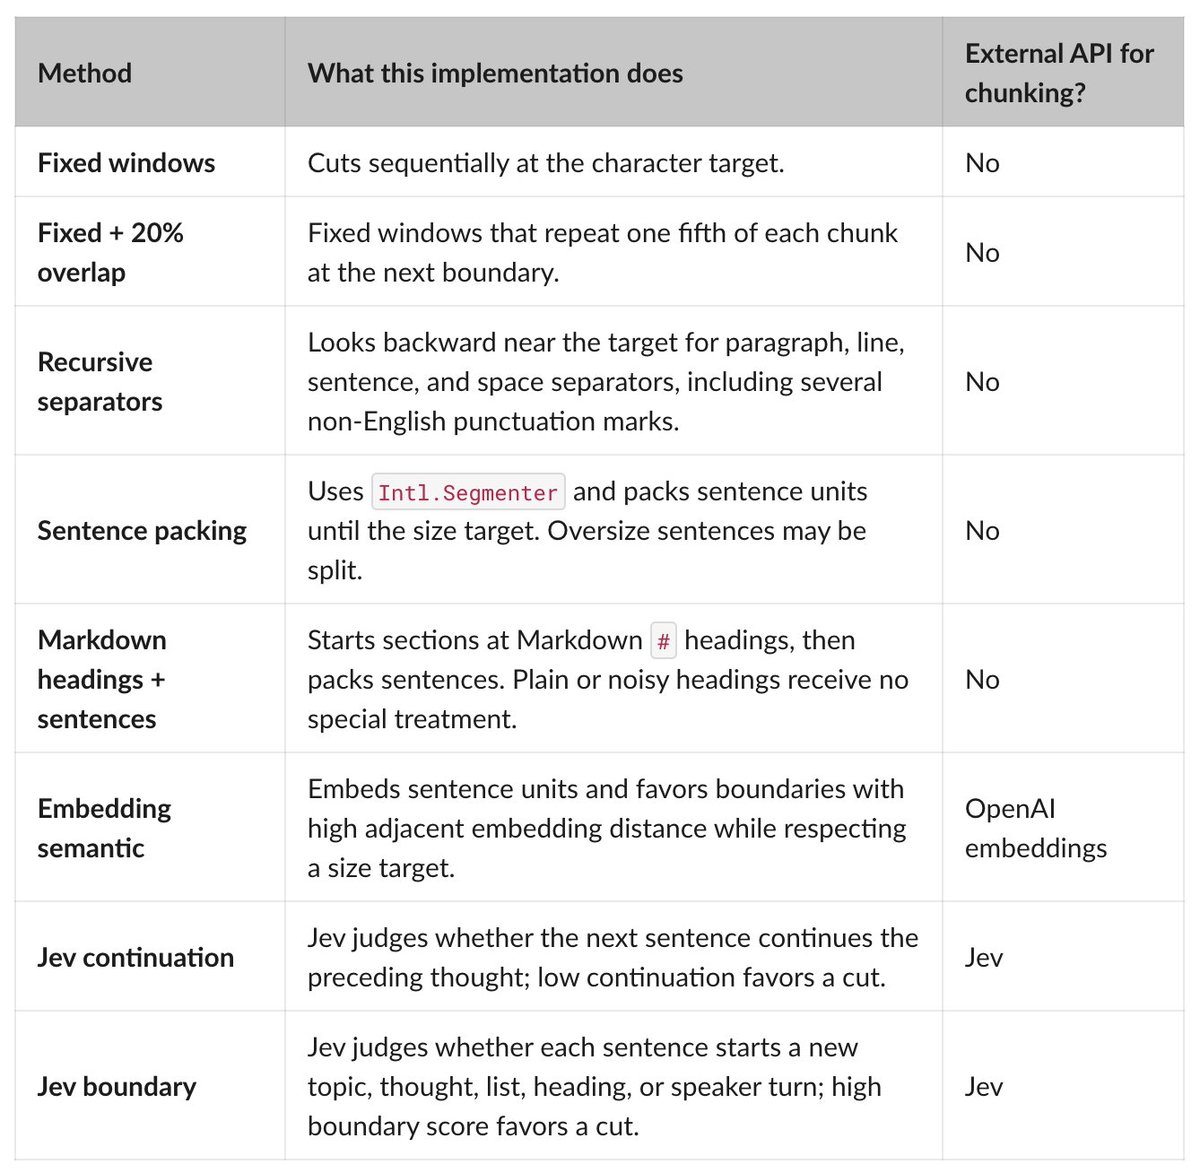
Right now, the popular ways of chunking are still a bit iffy. It's either too expensive (embedding based), or too deterministic (markdown heading based) or too vibes-based (sliding window chunking, fixed length chunking)
In all of these cases what we were seeing is that the chunks always had some issues.
Photo 2. Table. Method | What this implementation does | External API for chunking?. Fixed windows | Cuts sequentially at the character target. | No. Fixed + 20% overlap | Fixed windows that repeat one fifth of each chunk at the next boundary. | No. Recursive separators | Looks backward near the target for paragraph, line, sentence, and space separators, including several non-English punctuation marks. | No. Sentence packing | Uses Intl.Segmenter and packs sentence units until the size target. Oversize sentences may be split. | No. Markdown headings + sentences | Starts sections at Markdown # headings, then packs sentences. Plain or noisy headings receive no special treatment. | No. Embedding semantic | Embeds sentence units and favors boundaries with high adjacent embedding distance while respecting a size target. | OpenAI embeddings. Jev continuation | Jev judges whether the next sentence continues the preceding thought; low continuation favors a cut. | Jev. Jev boundary | Jev judges whether each sentence starts a new topic, thought, list, heading, or speaker turn; high boundary score favors a cut. | Jev.
With Jev, we can ask whether each sentence continues the previous thought or starts a new one, then use those answers to choose chunk boundaries near a target size.
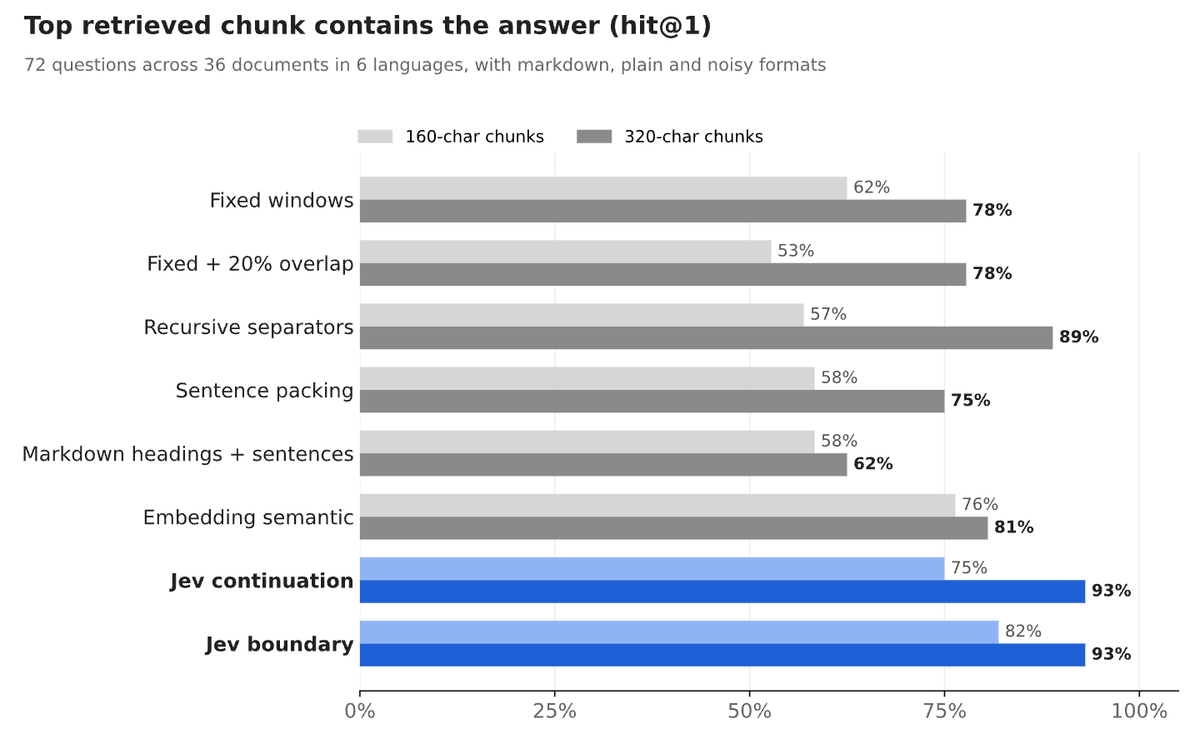
We built an internal benchmark with messy data, markdown data, and also multi-lingual data.
Photo 3. Bar chart. Title: Top retrieved chunk contains the answer (hit@1). Subtitle: 72 questions across 36 documents in 6 languages, with markdown, plain and noisy formats. Legend: light bars 160-char chunks; dark bars 320-char chunks. Approximate hit@1: Fixed windows 62% / 78%; Fixed + 20% overlap 53% / 78%; Recursive separators 57% / 89%; Sentence packing 58% / 75%; Markdown headings + sentences 58% / 62%; Embedding semantic 76% / 81%; Jev continuation 75% / 93%; Jev boundary 82% / 93%.
Jev is pretty clearly the SOTA at chunking
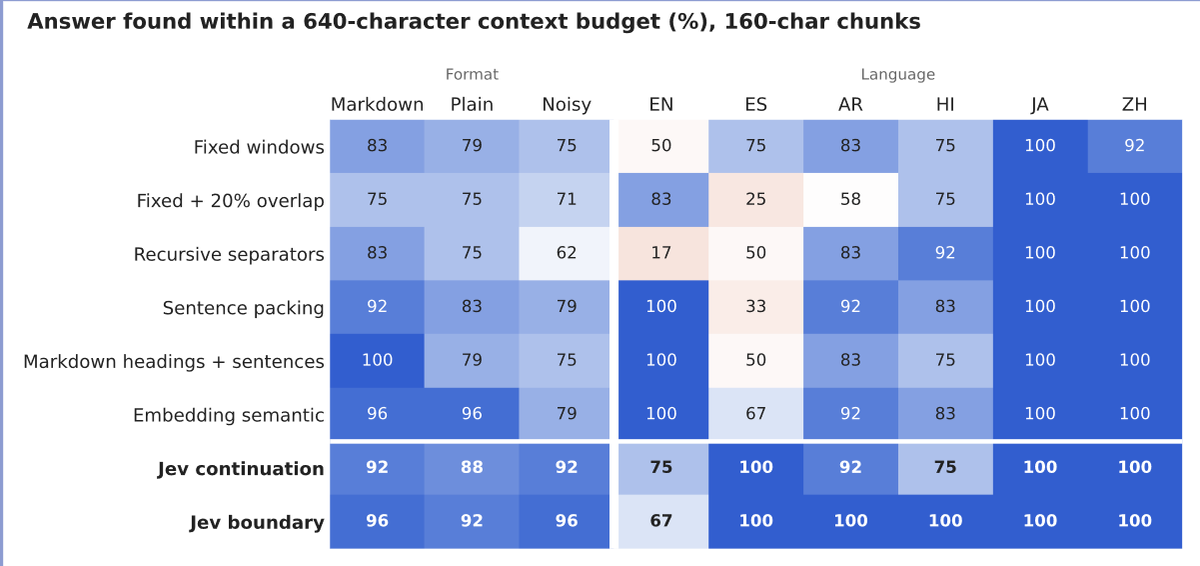
multi-lingual chunking is especially hard because the semantic boundaries are not very well defined. In many languages we put english words in the middle, or the other way around.
Jev was able to perform pretty good even in these multi-lingual use cases :)
Photo 4. Heatmap table. Title: Answer found within a 640-character context budget (%), 160-char chunks. Columns Format: Markdown, Plain, Noisy; Language: EN, ES, AR, HI, JA, ZH. Rows: Fixed windows 83 79 75 50 75 83 75 100 92; Fixed + 20% overlap 75 75 71 83 25 58 75 100 100; Recursive separators 83 75 62 17 50 83 92 100 100; Sentence packing 92 83 79 100 33 92 83 100 100; Markdown headings + sentences 100 79 75 100 50 83 75 100 100; Embedding semantic 96 96 79 100 67 92 83 100 100; Jev continuation 92 88 92 75 100 92 75 100 100; Jev boundary 96 92 96 67 100 100 100 100 100.
(Shoutout to @trychroma for this way of thinking / benchmarking chunks - we took this as a reference to figure out "What is good chunking" https://www.trychroma.com/research/evaluating-chunking)
The caveat, again, is cost. Jev is MUCH more expensive than other chunking methods (mainly because they are... essentially free)
But, Jev is the best chunker.
cost per 1k docs rule-based $0.008 ██ embedding semantic $0.011 ██▌ jev continuation $0.080 ██████████████████٠ jev boundary $0.087 ████████████████████
Cleaning up context before observation
Right now, for pretty much all memory cases, memory generation can get a bit expensive because of two things:
- A model has to look through pretty much all context, so inference is run twice
- In order to learn / register something, you need to know what's already learnt. You can't just remember a name every time you see it, you need to know if you already know the name, different name, etc.
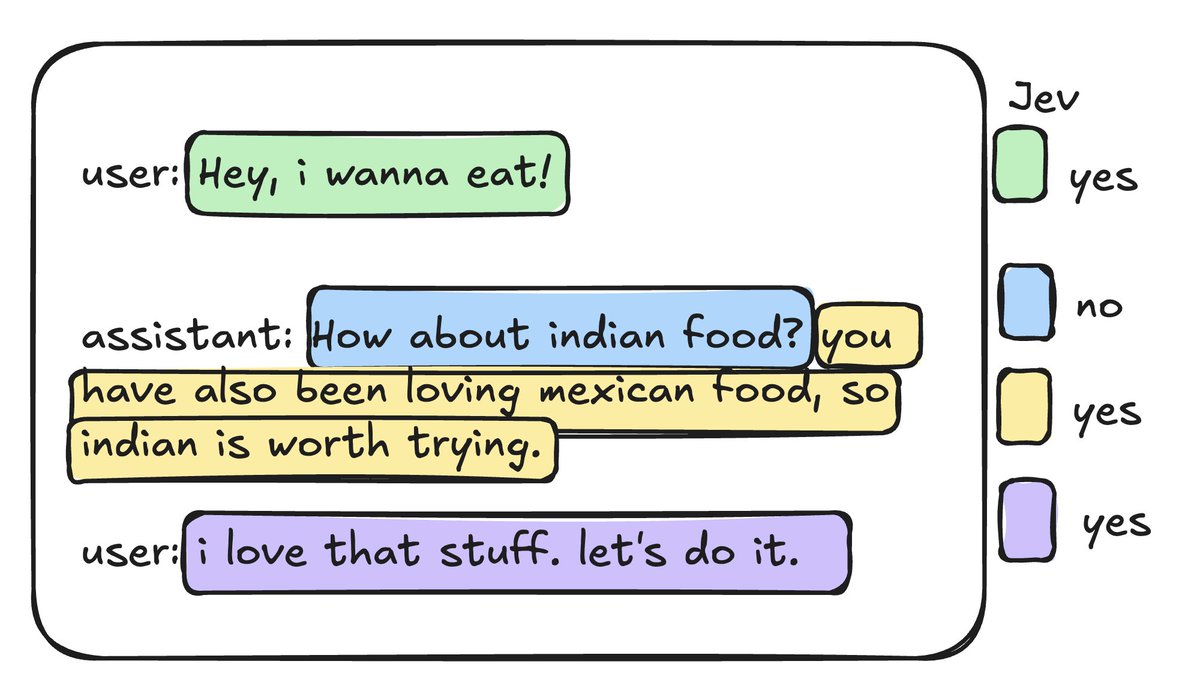
Most of the conversation or document is not even important for memory. It is headings, audio checks, "no action items," and talk that can stay searchable as source text. The idea was to put Jev in front of that call. Split the document into sentences, ask a yes/no (Noul) on each: should this go to the extractor at all? remove everything else.
Basically a cheap filter before things go into the observer model. On our internal benchmark, Jev was able to save us 58% of content tokens!! This means that we could literally spend half as much for theoretically just benefits!
The catch
However, obviously, this cut is not always free. Jev was good at removing a lot of this context, but removing some sentences independently seems to be the wrong direction, because of contextuality.
One example of this is assistant turns - Just trimming parts of it can damage the actual semantic meaning, which could be bad.
Photo 5. Diagram. Chat excerpt graded by Jev. user: Hey, i wanna eat! (yes). assistant: How about indian food? (no) you have also been loving mexican food, so indian is worth trying. (yes). user: i love that stuff. let's do it. (yes). Legend titled Jev maps green/yellow/purple spans to yes and the blue assistant suggestion span to no.
At the start of a legal document, or a conversation, a certain line/topic/word may not be useful, but it could be referenced sometime later on. We could not reliably figure out how to give Jev this full context because it's classifying sentences.
Even doing it in different ways had various problems of the same nature, so, as of right now, Jev is not a very good compactor for memory!
Because we have a small specialized model doing the learnings (learner-1 https://x.com/supermemory/status/2097035274094272935), observation is insanely cheap anyways, so all roads lead to using @supermemory for memory :) if you're building an agent you should use it.
Having decisions in the harness made by Jev
One of the product lines we work on at supermemory is plugins for all popular agents. (The most popular and my favorite one is claude code - check it out https://supermemory.ai/docs/integrations/claude-code)
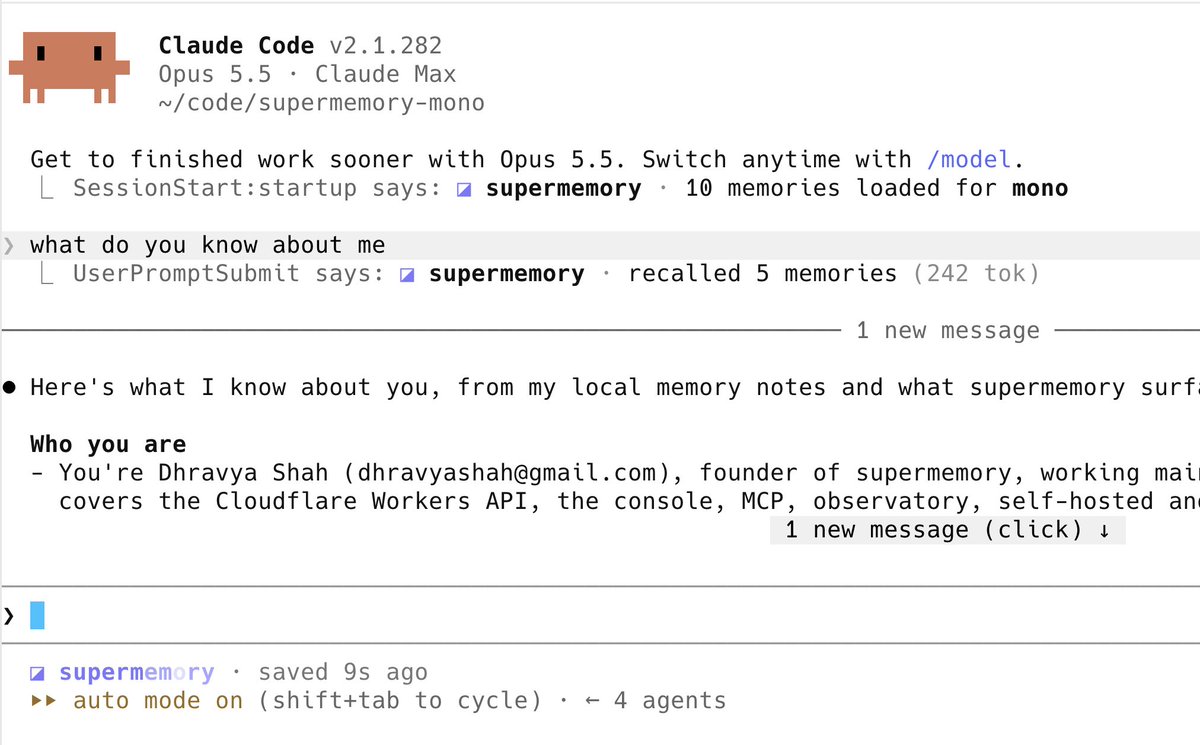
It automatically injects tokens to claude code to drive better outputs and improve personalization without damaging the context (avg tokens injected is 250 tokens, and you'll always know when it does)
Photo 6. Screenshot. Claude Code v2.1.282, Opus 5.5 + Claude Max, ~/code/supermemory-mono. Banner: Get to finished work sooner with Opus 5.5. Switch anytime with /model. SessionStart:startup says: supermemory - 10 memories loaded for mono. User prompt: what do you know about me. UserPromptSubmit says: supermemory - recalled 5 memories (242 tok). Assistant reply begins: Here's what I know about you, from my local memory notes and what supermemory surf... Who you are: You're Dhravya Shah (dhravyashah@gmail.com), founder of supermemory, working mai... covers the Cloudflare Workers API, the console, MCP, observatory, self-hosted an... Status: supermemory · saved 9s ago; auto mode on (shift+tab to cycle) · 4 agents.
We tried using Jev to take decisions at a claude code UserPromptSubmit hook, maybe it can figure out whether memory is needed or not for this query, but it still being a hook deciding the injection.
I have spoken a lot about my opinion on hooks vs tools for giving the model memory and context - But the TLDR of it is that I believe models are very bad at deciding when some memory should be helpful, but are getting better at longer context.
we try to provide a magical experience with supermemory - especially in plugins where we can build them specific to the harness. You should try our claude code plugin!
So, we don't want the model to decide when to bring in memories. Having jev decide feels really good!
Some people mention that they sometimes don't want the model to use memories for certain questions. Because Jev is just taking the decision to search or not, the user can literally just say "without using memory, tell me..."
And Jev would decide to not use the memory (without a tool call, in UserPromptSubmit hook.
So, Jev is the perfect solution for making ad-hoc decisions on the harness, improving user love & satisfaction.
Closing it out
Jev is an incredible new model. There's a lot of hype and most of it is justified! It can completely change a lot of the parts of how people do memory.
At the same time, It's not perfect for everything yet!
We have already started replacing a lot of our pipeline with decision models, and will continue doing work and research on them and writing about them! We also found ways to make supermemory much cheaper through Jev... more about that soon.
I'm biased, but if you're doing any context work (Memory, Retrieval, filesystems, even markdown), you should probably use @supermemory!
Cover / card image. White field with bold black text: I played with / [cube logo] jev. it changes / memory. Bottom-right supermemory wordmark with sparkle mark.